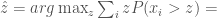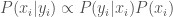Digifesto

Formalizing welfare implications of price discrimination based on personal information

In my last post I formalized Richard Posner’s 1981 argument concerning the economics of privacy. This is just one case of the economics of privacy. A more thorough analysis of the economics of privacy would consider the impact of personal information flow in more aspects of the economy. So let’s try another one.

One major theme of Shapiro and Varian’s Information Rules (1999) is the importance of price differentiation when selling information goods and how the Internet makes price differentiation easier than ever. Price differentiation likely motivates much of the data collection on the Internet, though it’s a practice that long predates the Internet. Shapiro and Varian point out that the “special offers” one gets from magazines for an extension to a subscription may well offer a personalized price based on demographic information. What’s more, this personalized price may well be an experiment, testing for the willingness of people like you to pay that price. (See Acquisti and Varian, 2005 for a detailed analysis of the economics of conditioning prices on purchase history.)

The point of this post is to analyze how a firm’s ability to differentiate its prices is a function of the knowledge it has about its customers and hence outcomes change with the flow of personal information. This makes personalized price differentiation a sub-problem of the economics of privacy.

To see this, let’s assume there are a number of customers for a job, i \in I, where the number of customers is n = \left\vert{I}\right\vert. Let’s say each has a willingness to pay for the firm’s product, x_i. Their willingness to pay is sampled from an underlying probability distribution x_i \sim X.

Note two things about how we are setting up this model. The first is that it closely mirrors our formulation of Posner’s argument about hiring job applicants. Whereas before the uncertain personal variable was aptitude for a job, in this case it is willingness to pay.

The second thing to note is that whereas it is typical to analyze price differentiation according to a model of supply and demand, here we are modeling the distribution of demand as a random variable. This is because we are interested in modeling information flow in a specific statistical sense. What we will find is that many of the more static economic tools translate well into a probabilistic domain, with some twists.

Now suppose the firm knows X but does not know any specific x_i. Knowing nothing to differentiate the customers, the firm will choose to offer the product at the same price z to everybody. Each customer will buy the product if x_i > z, and otherwise won’t. Each customer that buys the product contributes z to the firm’s utility (we are assuming an information good with near zero marginal cost). Hence, the firm will pick \hat z according to the following function:

\hat z = arg \max_z E[\sum_i z [x_i > z]] =

\hat z = arg \max_z \sum_i E[z [x_i > z]] =

\hat z = arg \max_z \sum_i z E[[x_i > z]] =

\hat z = arg \max_z \sum_i z P(x_i > z) =

\hat z = arg \max_z \sum_i z P(X > z)

Where [x_i > z] is a function with value 1 if x_i > z and 0 otherwise; this is using Iverson bracket notation.

This is almost identical to the revenue-optimizing strategy of price selection more generally, and it has a number of similar properties. One property is that for every customer for whom x_i > z, there is a consumer surplus of utility $late x_i – z$, that feeling of joy the customer gets for having gotten something valuable for less than they would have been happy to pay for it. There is also the deadweight loss of customers for whom z > x_i. These customers get 0 utility from the product and pay nothing to the producer despite their willingness to pay.

Now consider the opposite extreme, wherein the producer knows the willingness to pay of each customer x_i and can pick a personalized price z_i accordingly. The producer can price z_i = x_i - \epsilon, effectively capturing the entire demand \sum_i x_i as producer surplus, while reducing all consumer surplus and deadweight loss to zero.

What are the welfare implications of the lack of consumer privacy?

Like in the case of Posner’s employer, the real winner here is the firm, who is able to capture all the value added to the market by the increased flow of information. In both cases we have assumed the firm is a monopoly, which may have something to do with this result.

As for consumers, there are two classes of impact. For those with x_i > \hat z, having their personal willingness to pay revealed to the firm means that they lose their consumer surplus. Their welfare is reduced.

For those consumers with x_i < \hat z, these discover that they now can afford the product as it is priced close to their willingness to pay.

Unlike in Posner's case, "the people" here are more equal when their personal information is revealed to the firm because now the firm is extracting every spare ounce of joy it can from each of them, whereas before some consumers were able to enjoy low prices relative to their idiosyncratically high appreciation for the good.

What if the firm has access to partial information about each consumer y_i that is a clue to their true x_i without giving it away completely? Well, since the firm is a Bayesian reasoner they now have the subjective belief P(x_i \vert y_i) and will choose each z_i in a way that maximizes their expected profit from each consumer.

z_i = arg \max_z E[z [P(x_i > z \vert y_i)]]

The specifics of the distributions X, Y, and P(Y | X) all matter for the particular outcomes here, but intuitively one would expect the results of partial information to fall somewhere between the extremes of undifferentiated pricing and perfect price discrimination.

Perhaps the more interesting consequence of this analysis is that the firm has, for each consumer, a subjective probabilistic distribution of that consumer’s demand. Their best strategy for choosing the personalized price is similar to that of choosing a price for a large uncertain consumer demand base, only now the uncertainty is personalized. This probabilistic version of classic price differentiation theory may be more amenable to Bayesian methods, data science, etc.

References

Acquisti, A., & Varian, H. R. (2005). Conditioning prices on purchase history. Marketing Science, 24(3), 367-381.

Shapiro, C., & Varian, H. R. (1998). Information rules: a strategic guide to the network economy. Harvard Business Press.

Formalizing Posner’s economics of privacy argument

I’d like to take a more formal look at Posner’s economics of privacy argument, in light of other principles in economics of information, such as those in Shapiro and Varian’s Information Rules.

By “formal”, what I mean is that I want to look at the mathematical form of the argument. This is intended to strip out some of the semantics of the problem, which in the case of economics of privacy can lead to a lot of distracting anxieties, often for legitimate ethical reasons. However, there are logical realities that one must face despite the ethical conundrums they cause. Indeed, if there weren’t logical constraints on what is possible, then ethics would be unnecessary. So, let’s approach the blackboard, shall we?

In our interpretation of Posner’s argument, there are a number of applicants for a job, i \in I, where the number of candidates is n = \left\vert{I}\right\vert. Let’s say each is capable of performing at a certain level based on their background and aptitude, x_i. Their aptitude is sampled from an underlying probability distribution x_i \sim X.

There is an employer who must select an applicant for the job. Let’s assume that their capacity to pay for the job is fixed, for simplicity, and that all applicants are willing to accept the wage. The employer must pick an applicant i and gets utility x_i for their choice. Given no information on which to base her choice, she chooses a candidate randomly, which is equivalent to sampling once from X. Her expected value, given no other information on which to make the choice, is E[X]. The expected welfare of each applicant is their utility from getting the job (let’s say it’s 1 for simplicity) times their probability of being picked, which comes to \frac{1}{n}.

Now suppose the other extreme: the employer has perfect knowledge of the abilities of the applicants. Since she is able to pick the best candidate, her utility is \max x_i. Let \hat i = arg\max_{i \in I} x_i. Then the utility for applicant \hat i is 1, and it is 0 for the other applicants.

Some things are worth noting about this outcome. There is more inequality. All expected utility from the less qualified applicants has moved to the most qualified applicant. There is also an expected surplus of (\max x_i) - E[X] that accrues to the totally informed employer. One wonders if a “safety net” were to be provided those who have lost out in this change; if it could be, it would presumably be funded from this surplus. If the surplus were entirely taxed and redistributed among the applicants who did not get the job, it would provide each rejected applicant with \frac{(\max x_i) - E[X]}{n-1} utility. Adding a little complexity to the model we could be more precise by computing the wage paid to the worker and identify whether redistribution could potentially recover the losses of the weaker applicants.

What about intermediary conditions? These get more analytically complex. Suppose that each applicant i produces an application y_i which is reflective of their abilities. When the employer makes her decision, her expectation of the performance of each applicant is

P(x_i \vert y_i) \propto P(y_i \vert x_i)P(x_i)

because naturally the employer is a Bayesian reasoner. She makes her decision by maximizing her expected gain, based on this evidence:

arg\max E[P(x_i \vert y_i)] =

arg\max \sum_{x_i} x_i p(x_i \vert y_i) =

arg\max \sum_{x_i} x_i p(y_i \vert x_i) p(x_i)

The particulars of the distributions X and Y and especially P(Y \vert X) matter a great deal to the outcome. But from the expanded form of the equation we can see that the more revealing y_i is about x_i< the more the likelihood term p(y_i \vert x_i) will overcome the prior expectations. It would be nice to be able to capture the impact of this additional information in a general way. One would think that providing limited information about applicants to the employer would result in an intermediate outcome. Under reasonable assumptions, more qualified applicants would be more likely to be hired and the employer would accrue more value from the work.

What this goes to show is how ones evaluation of Posner's argument about the economics of privacy really has little to do with the way one feels about privacy and much more to do with how one feels about the equality and economic surplus. I've heard that a similar result has been discovered by Solon Barocas, though I'm not sure where in his large body of work to find it.

From information goods to information services

Continuing to read through Information Rules, by Shapiro and Varian (1999), I’m struck once again by its clear presentation and precise wisdom. Many of the core principles resonate with my experience in the software business when I left it in 2011 for graduate school. I think it’s fair to say that Shapiro and Varian anticipated the following decade of  the economics of content and software distribution.

What they don’t anticipate, as far as I can tell, is what has come to dominate the decade after that, this decade. There is little in Information Rules that addresses the contemporary phenomena of cloud computing and information services, such as Software-as-a-Service, Platforms-as-a-Service, and Infrastructure-as-a-Service. Yet these are clearly the kinds of services that have come to dominate the tech market.

That’s an opening. According to a business manager in 2014, there’s no book yet on how to run an SaaS company. While sure that if I were slightly less lazy I would find several, I wonder if they are any good. By “any good”, I mean would they hold up to scientific standards in their elucidation of economic law, as opposed to being, you know, business books.

One of the challenges of working on this which has bothered me since I first became curious about these problems is that there is not very good elegant formalism available for representing competition between computing agents. The best that’s out there is probably in the AI literature. But that literature is quite messy.

Working up from something like Information Rules might be a more promising way of getting at some of these problems. For example, Shapiro and Varian start from the observation that information goods have high fixed (often, sunk) costs and low marginal costs to reproduce. This leads them to the conclusion that the market cannot look like a traditional competitive market with multiple firms selling similar goods but rather must either have a single dominant firm or a market of many similar but differentiated products.

The problem here is that most information services, even “simple” ones like a search engine, are not delivering a good. They are being responsive to some kind of query. The specific content and timing of the query, along with the state of the world at the time of the query, are unique. Consumers may make the same query with varying demand. The value-adding activity is not so much creating the good as it is selecting the right response to the query. And who can say how costly this is, marginally?

On the other hand, this framing obscures something important about information goods, which is that all information goods are, in a sense, a selection of bits from the wide range of possible bits one might send or receive. This leads to my other frustration with information economics, which is that it is insufficiently tied to the statistical definition of information and the modeling tools that have been built around it. This is all the more frustrating because I suspect that in advanced industrial settings these connections have been made and are used with confidence. However, it had been slow to make it into mainstream understanding. There’s another opportunity here.

Shapiro and Varian: scientific “laws of economics”

I’ve been amiss in not studying Shapiro and Varian’s Information Rules: A Strategic Guide to the Network Economy (1998, link) more thoroughly. In my years in the tech industry and academic study, there are few sources that deal with the practical realities of technology and society as clearly as Shapiro and Varian. As I now turn my attention more towards the rationale for various forms of information law and find how much of it is driven by considerations of economics, I have to wonder why this was not something I’ve given more emphasis in my graduate study so far.

The answer that comes immediately to mind is that throughout my academic study of the past few years I’ve encountered a widespread hostility to economics from social scientists of other disciplines. This hostility resembles, though is somewhat different from, the hostility social scientists other other stripes have had (in my experience) for engineers. The critiques have been along the lines that economists are powerful disproportionately to the insight provided by the field, that economists are focused too narrowly on certain aspects of social life to the exclusion of others that are just as important, that economists are arrogant in their belief that their insights about incentives apply to other areas of social life besides the narrow concerns of the economy, that economists mistakenly think their methods are more scientific or valid than other social scientists, that economics is in the business of enshrining legal structures into place that give their conclusions more predictive power than they would have in other legal regimes and, as of the most recent news cycle, that the field of economics is hostile to women.

This is a strikingly familiar pattern of disciplinary critique, as it seems to be the same one levied at any field that aims to “harden” inquiry into social life. The encroachment of engineering disciplines and physicists into social explanation has come with similar kinds of criticism. These criticisms, it must be noted, contain at least one contradiction: should economists be concerned about issues besides the economy, or not? But the key issue, as with most disciplinary spats, is the politics of a lot of people feeling dismissed or unheard or unfunded.

Putting all this aside, what’s interesting about the opening sections of Shapiro and Varian’s book is their appeal to the idea of laws of economics, as if there were such laws analogous to laws of physics. The idea is that trends in the technology economy are predictable according to these laws, which have been learned through observation and formalized mathematically, and that these laws should therefore be taught for the benefit of those who would like to participate successfully in that economy.

This is an appealing idea, though one that comes under criticism, you know, from the critics, with a predictability that almost implies a social scientific law. This has been a debate going back to discussions of Marx and communism. Early theorists of the market declared themselves to have discovered economic laws. Marx, incidentally, also declared that he had discovered (different) economic laws, albeit according to the science of dialectical materialism. But the latter declared that the former economic theories hide the true scientific reality of the social relations underpinning the economy. These social relations allowed for the possibility of revolution in a way that an economy of goods and prices abstracted from society did not.

As one form of the story goes, the 20th century had its range of experiments with ways of running an economy. Those most inspired by Marxism had mass famines and other unfortunate consequences. Those that took their inspiration from the continually evolving field of increasingly “neo”-classical economics, with its variations of Keynesianism, monetarism, and the rest, had some major bumps (most recently the 2008 financial crisis) but tends to improve over time with historical understanding and the discovery of, indeed, laws of economics. And this is why Janet Yellen and Mario Draghi are now warning against removing the post-crisis financial market regulations.

This offers an anecdotal counter to the narrative that all economists ever do is justify more terrible deregulation at the expense of the lived experience of everybody else. The discovery of laws of economics can, indeed, be the basis for economic regulation; in fact this is often the case. In point of fact, it may be that this is one of the things that tacitly motivates the undermining of economic epistemology: the fact that if the laws of economics were socially determined to be true, like the laws of physics, such that everybody ought to know them, it would lead to democratic will for policies that would be opposed to the interests of those who have heretofore enjoyed the advantage of their privileged (i.e., not universally shared) access to the powerful truth about markets, technology, etc.

Which is all to say: I believe that condemnations of economics as a field are quite counterproductive, socially, and that the scientific pursuit of the discovery of economic laws is admirable and worthy. Those that criticize economics for this ambition, and teach their students to do so, imperil everyone else and should stop.

Reason returns to Berkeley

I’ve been struck recently by a subtle shift in messaging at UC Berkeley since Carol T. Christ has become the university’s Chancellor. Incidentally, she is the first woman chancellor of the university, with a research background in Victorian literature. I think both of these things may have something to do with the bold choice she’s made in recent announcements: the inclusion of reason as among the University’s core values.

Notably, the word has made its appearance next to three other terms that have had much more prominence in the university in recent years: equity, inclusion, and diversity. For example, in the following statements:

In “Thoughts on Charlottesville”:

We must now come together to oppose what are dangerous threats to the values we hold dear as a democracy and as a nation. Our shared belief in reason, diversity, equity, and inclusion is what animates and supports our campus community and the University’s academic mission. Now, more than ever, those values are under assault; together we must rise to their defense.

And, strikingly, this message on “Free Speech”:

Nonetheless, defending the right of free speech for those whose ideas we find offensive is not easy. It often conflicts with the values we hold as a community—tolerance, inclusion, reason and diversity. Some constitutionally-protected speech attacks the very identity of particular groups of individuals in ways that are deeply hurtful. However, the right response is not the heckler’s veto, or what some call platform denial. Call toxic speech out for what it is, don’t shout it down, for in shouting it down, you collude in the narrative that universities are not open to all speech. Respond to hate speech with more speech.

The above paragraph comes soon after this one, in which Chancellor Christ defends Free Speech on Millian philosophical grounds:

The philosophical justification underlying free speech, most powerfully articulated by John Stuart Mill in his book On Liberty, rests on two basic assumptions. The first is that truth is of such power that it will always ultimately prevail; any abridgement of argument therefore compromises the opportunity of exchanging error for truth. The second is an extreme skepticism about the right of any authority to determine which opinions are noxious or abhorrent. Once you embark on the path to censorship, you make your own speech vulnerable to it.

This slight change in messaging strikes me as fundamentally wise. In the past year, the university has been wracked by extreme passions and conflicting interests, resulting in bad press externally and I imagine discomfort internally. But this was not unprecedented; the national political bifurcation could take hold at Berkeley precisely because it had for years been, with every noble intention, emphasizing inclusivity and equity without elevating a binding agent that makes diversity meaningful and productive. This was partly due to the influence of late 20th century intellectual trends that burdened “reason” with the historical legacy of those regimes that upheld it as a virtue, which tended to be white and male. There was a time when “reason” was so associated with these powers that the term was used for the purposes of exclusion–i.e. with the claim that new entrants to political and intellectual power were being “unreasonable”.

Times have changed precisely because the exclusionary use of “reason” was a corrupt one; reason in its true sense is impersonal and transcends individual situation even as it is immanent in it. This meaning of reason would be familiar to one steeped in an older literature.

Carol Christ’s wording reflects a 21st century theme which to me gives me profound confidence in Berkeley’s future: the recognition that reason does not oppose inclusion, but rather demands it, just as scientific logic demands properly sampled data. Perhaps the new zeitgeist at Berkeley has something to do with the new Data Science undergraduate curriculum. Given the state of the world, I’m proud to see reason make a comeback.

Notes on Posner’s “The Economics of Privacy” (1981)

Lately my academic research focus has been privacy engineering, the designing of information processing systems that preserve privacy of their users. I have been looking the problem particularly through the lens of Contextual Integrity, a theory of privacy developed by Helen Nissenbaum (2004, 2009). According to this theory, privacy is defined as appropriate information flow, where “appropriateness” is determined relative to social spheres (such as health, education, finance, etc.) that have evolved norms based on their purpose in society.

To my knowledge most existing scholarship on Contextual Integrity is comprised by applications of a heuristic process associated with Contextual Integrity that evaluates the privacy impact of new technology. In this process, one starts by identifying a social sphere (or context, but I will use the term social sphere as I think it’s less ambiguous) and its normative structure. For example, if one is evaluating the role of a new kind of education technology, one would identify the roles of the education sphere (teachers, students, guardians of students, administrators, etc.), the norms of information flow that hold in the sphere, and the disruptions to these norms the technology is likely to cause.

I’m coming at this from a slightly different direction. I have a background in enterprise software development, data science, and social theory. My concern is with the ways that technology is now part of the way social spheres are constituted. For technology to not just address existing norms but deal adequately with how it self-referentially changes how new norms develop, we need to focus on the parts of Contextual Integrity that have heretofore been in the background: the rich social and metaethical theory of how social spheres and their normative implications form.

Because the ultimate goal is the engineering of information systems, I am leaning towards mathematical modeling methods that trade well between social scientific inquiry and technical design. Mechanism design, in particular, is a powerful framework from mathematical economics that looks at how different kinds of structures change the outcomes for actors participating in “games” that involve strategy action and information flow. While mathematical economic modeling has been heavily critiqued over the years, for example on the basis that people do not act with the unbounded rationality such models can imply, these models can be a first step and valuable in a technical context especially as they establish the limits of a system’s manipulability by non-human actors such as AI. This latter standard makes this sort of model more relevant than it has ever been.

This is my roundabout way of beginning to investigate the fascinating field of privacy economics. I am a new entrant. So I found what looks like one of the earliest highly cited articles on the subject written by the prolific and venerable Richard Posner, “The Economics of Privacy”, from 1981.
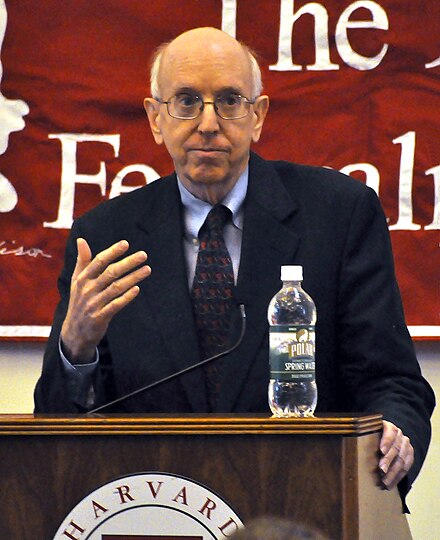
Richard Posner, from Wikipedia

Wikipedia reminds me that Posner is politically conservative, though apparently he has changed his mind recently in support of gay marriage and, since the 2008 financial crisis, the laissez faire rational choice economic model that underlies his legal theory. As I have mainly learned about privacy scholarship from more left-wing sources, it was interesting reading an article that comes from a different perspective.

Posner’s opening position is that the most economically interesting aspect of privacy is the concealment of personal information, and that this is interesting mainly because privacy is bad for market efficiency. He raises examples of employers and employees searching for each other and potential spouses searching for each other. In these cases, “efficient sorting” is facilitated by perfect information on all sides. Privacy is foremost a way of hiding disqualifying information–such as criminal records–from potential business associates and spouses, leading to a market inefficiency. I do not know why Posner does not cite Akerlof (1970) on the “market for ‘lemons'” in this article, but it seems to me that this is the economic theory most reflective of this economic argument. The essential question raised by this line of argument is whether there’s any compelling reason why the market for employees should be any different from the market for used cars.

Posner raises and dismisses each objective he can find. One objection is that employers might heavily weight factors they should not, such as mental illness, gender, or homosexuality. He claims that there’s evidence to show that people are generally rational about these things and there’s no reason to think the market can’t make these decisions efficiently despite fear of bias. I assume this point has been hotly contested from the left since the article was written.

Posner then looks at the objection that privacy provides a kind of social insurance to those with “adverse personal characteristics” who would otherwise not be hired. He doesn’t like this argument because he sees it as allocating the costs of that person’s adverse qualities to a small group that has to work with that person, rather than spreading the cost very widely across society.

Whatever one thinks about whose interests Posner seems to side with and why, it is refreshing to read an article that at the very least establishes the trade offs around privacy somewhat clearly. Yes, discrimination of many kinds is economically inefficient. We can expect the best performing companies to have progressive hiring policies because that would allow them to find the best talent. That’s especially true if there are large social biases otherwise unfairly skewing hiring.

On the other hand, the whole idea of “efficient sorting” assumes a policy-making interest that I’m pretty sure logically cannot serve the interests of everyone so sorted. It implies a somewhat brutally Darwinist stratification of personnel. It’s quite possible that this is not healthy for an economy in the long term. On the other hand, in this article Posner seems open to other redistributive measures that would compensate for opportunities lost due to revelation of personal information.

There’s an empirical part of the paper in which Posner shows that percentage of black and Hispanic populations in a state are significantly correlated with existence of state level privacy statutes relating to credit, arrest, and employment history. He tries to spin this as an explanation for privacy statutes as the result of strongly organized black and Hispanic political organizations successfully continuing to lobby in their interest on top of existing anti-discrimination laws. I would say that the article does not provide enough evidence to strongly support this causal theory. It would be a stronger argument if the regression had taken into account the racial differences in credit, arrest, and employment state by state, rather than just assuming that this connection is so strong it supports this particular interpretation of the data. However, it is interesting that this variable ways more strongly correlated with the existence of privacy statutes than several other variables of interest. It was probably my own ignorance that made me not consider how strongly privacy statutes are part of a social justice agenda, broadly speaking. Considering that disparities in credit, arrest, and employment history could well be the result of other unjust biases, privacy winds up mitigating the anti-signal that these injustices have in the employment market. In other words, it’s not hard to get from Posner’s arguments to a pro-privacy position based of all things on market efficiency.

It would be nice to model that more explicitly, if it hasn’t been done yet already.

Posner is quite bullish on privacy tort, thinking that it is generally not so offensive from an economic perspective largely because it’s about preventing misinformation.

Overall, the paper is a valuable starting point for further study in economics of privacy. Posner’s economic lens swiftly and clearly puts the trade-offs around privacy statutes in the light. It’s impressively lucid work that surely bears directly on arguments about privacy and information processing systems today.

References

Akerlof, G. A. (1970). The market for” lemons”: Quality uncertainty and the market mechanism. The quarterly journal of economics, 488-500.

Nissenbaum, H. (2004). Privacy as contextual integrity. Wash. L. Rev., 79, 119.

Nissenbaum, H. (2009). Privacy in context: Technology, policy, and the integrity of social life. Stanford University Press.

Posner, R. A. (1981). The economics of privacy. The American economic review, 71(2), 405-409. (jstor)

Ulanowicz on thermodynamics as phenomenology

I’ve finally worked my way back to Ulanowicz, whose work so intrigued me when I first encountered it over four years ago. Reading a few of his papers on theoretical ecology gave the impression that he is both a serious scientist and onto something profound. Now I’m reading Growth and Development: Ecosystems Phenomenology (1986), which looked to be the most straightforwardly mathematical introduction to his theory of ecosystem ascendancy, which is his theory of how ecosystems can grow and develop over time.

I am eager to get to the hard stuff, where he cashes out the theory in terms of matrix multiplication representing networks of energy flows. I see several parallels to my own work and I’m hoping there are hints in here about how I can best proceed.

But first I must note a few interesting ways in which Ulanowicz positions his argument.

One important one is that he uses the word “phenomenology” in the title and in the opening argument about the nature of thermodynamics. Thermodynamics, he argues, is unlike many other more reductionist parts of physics because it draws general statistical laws on microscopically observed systems which can be reduced to many different configurations of microphenomena. This gives it both a kind of empirical weakness compared to the lower-level laws; nevertheless there is a compelling universality to its descriptive power that informs the application of so many other more specialized sciences.

This resonates with many of the themes I’ve been exploring through my graduate study. Ulanowicz never cites Francisco Varela though the latter is almost a contemporary and similarly interested in combining principles of cybernetics with the life sciences (in Varela’s case, biology). Both Ulanowicz and Varela come to conclusions about the phenomenological nature of the life sciences which are unusual in the hard sciences.

Naturally, the case has been made that the social sciences are phenomenological as well, though generally these claims are made without a hope of making a phenomenological social science as empirically rigorous as ecology, let alone biology. Nevertheless Ulanowicz does hint, as does Varela, at the possibility of extending his models to social systems.

This is of course fascinating given the difficult problem of the “macro-micro link” (see Sawyer). Ecosystem size and the properties Ulanowicz derives about them are “emergent” properties of an ecosystem; his theory is I gather an attempt at a universal description of how these properties emerge.

Somehow, Ulanowicz manages to take on these problems without ever invoking the murky language of “complex adaptive systems”. This is, I suspect, a huge benefit to his work as he seems to write strictly as a scientist and does not mystify things by using undefined language of ‘complexity’.

It is a deeper technical dive than I’ve been used to for some time, but I’m very gratefully in a more technical academic milieu now than I’ve been in for several years. More soon.

References

Ulanowicz, Robert E. “Growth and development: A phenomenological perspective.” (1986).

Differing ethnographic accounts of the effectiveness of technology

I’m curious as I compare two recent papers, one by Christin [2017] and one by Levy [2015], both about the role of technology in society. and backed by ethnographic data.

What interests me is that the two papers both examine the use of algorithms in practice, but they differ in their account of the effectiveness of the algorithms used. Christin emphasizes the way web journalists and legal professionals deliberately undermine the impact of algorithms. Levy discusses how electronic monitoring achieves central organizational control over truckers.

I’m interested in the different framings because, as Christin points out, a central point of contention in the critical scholarship around data and algorithms is the effectiveness of the technology, especially “in practice”. Implicitly if not explicitly, if the technology is not as effective as its advocates say it is, then it is overhyped and this debunking is an accomplishment of the critical and often ethnographic field.

On the other hand, if the technology is effective at control, as Levy’s article argues that it is, then it poses a much more real managerialist threat to worker’s autonomy. Identifying that this is occurring is also a serious accomplishment of the ethnographic field.

What must be recognized, however, is that these two positions contradict each other, at least as general perspectives on data-collection and algorithmic decision-making. The use of a particular technology in a particular place cannot be both so ineffective as to be overhyped and so effective as to constitute a managerialist threat. The substance of the two critiques is at odds with each other, and they call for different pragmatic responses. The former suggests a rhetorical strategy of further debunking, the latter demands a material strategy of changing working conditions.

I have seen both strategies used in critical scholarship, sometimes even in the same article, chapter, or book. I have never seen critical scholars attempt to resolve this difference between themselves using their shared assumptions and methods. I’d like to see more resolution in the ethnographic field on this point.

Correction, 8/10/17:

The apparent tension is resolved on a closer reading of Christin (2017). The argument there is that technology (in the managerialist use common to both papers) is ineffective when its intended use is resisted by those being managed by it.

That shifts the ethnographic challenge to technology away from an attack on the technical quality of the work (which is a non-starter) to accomplish what it is designed to do, but rather on the uncontroversial proposition that the effectiveness of technology depends in part on assumptions on how it will be used, and that these assumptions can be violated.

The political question of to what extent these new technologies should be adopted can then be addressed straightforwardly in terms of whether or not it is fully and properly adopted, or only partially and improperly adopted. Using language like this would be helpful in bridging technical and ethnographic fields.

References

Christin, 2017. “Algorithms in practice: Comparing journalism and criminal justice.” (link)

Levy, 2015. “The Contexts of Control: Information, Power, and Truck-Driving Work.” (link)

legitimacy in peace; legitimacy in war

I recently wrote a reflection on the reception of Habermas in the United States and argued that the lack of intellectual uptake of his later work have been a problem with politics here. Here’s what I wrote, admittedly venting a bit:

In my experience, it is very difficult to find support in academia for the view that rational consensus around democratic institutions is a worthwhile thing to study or advocate for. Identity politics and the endless contest of perspectives is much more popular among students and scholars coming out of places like UC Berkeley. In my own department, students were encouraged to read Habermas’s early work in the context of the identity politics critique, but never exposed to the later work that reacted to these critiques constructively to build a theory that was specifically about pluralism, which is what identity politics need in order to unify as a legitimate state. There’s a sense in which the whole idea that one should continue an philosophical argument to the point of constructive agreement, despite the hard work and discipline that this demands, was abandoned in favor of an ideology of intellectual diversity that discouraged scrutiny and rigor across boundaries of identity, even in the narrow sense of professional or disciplinary identity.

Tapan Parikh succinctly made the point that Habermas’s philosophy may be too idealistic to ever work out:

“I still don’t buy it without taking history, race, class and gender into account. The ledger doesn’t start at zero I’m afraid, and some interests are fundamentally antagonistic.”

This objection really is the crux of it all, isn’t it? There is a contradiction between agreement, necessary for a legitimate pluralistic state, and antagonistic interests of different social identities, especially as they are historically and presently unequal. Can there ever be a satisfactory resolution? I don’t know. Perhaps the dialectical method will get us somewhere. (This is a blog after all; we can experiment here).

But first, a note on intellectual history, as part of the fantasy of this argument is that intellectual history matters for actual political outcomes. When discussing the origins of contemporary German political theory, we should acknowledge that post-War Germany has been profoundly interested in peace as it has experienced the worst of war. The roots of German theories of peace are in Immanual Kant’s work on “perpetual peace”, the hypothetical situation in which states are no longer at way. He wrote an essay about it in 1795, which by the way begins with this wonderful preface:

PERPETUAL PEACE

Whether this satirical inscription on a Dutch innkeeper’s sign upon which a burial ground was painted had for its object mankind in general, or the rulers of states in particular, who are insatiable of war, or merely the philosophers who dream this sweet dream, it is not for us to decide. But one condition the author of this essay wishes to lay down. The practical politician assumes the attitude of looking down with great self-satisfaction on the political theorist as a pedant whose empty ideas in no way threaten the security of the state, inasmuch as the state must proceed on empirical principles; so the theorist is allowed to play his game without interference from the worldly-wise statesman. Such being his attitude, the practical politician–and this is the condition I make–should at least act consistently in the case of a conflict and not suspect some danger to the state in the political theorist’s opinions which are ventured and publicly expressed without any ulterior purpose. By this clausula salvatoria the author desires formally and emphatically to deprecate herewith any malevolent interpretation which might be placed on his words.

When the old masters are dismissed as being irrelevant or dense, it denies them the credit for being very clever.

That said, I haven’t read this essay yet! But I have a somewhat informed hunch that more contemporary work that deals with the problems it raises directly make good headway on problem of political unity. For example, this article by Bennington (2012) “Kant’s Open Secret” is good and relevant to discussions of technical design and algorithmic governance. Cederman, who has been discussed here before, builds a computational simulation of peace inspired by Kant.

Here’s what I can sketch out, perhaps ignorantly. What’s at stake is whether antagonistic actors can resolve their differences and maintain peace. The proposed mechanism for this peace is some form of federated democracy. So to paint a picture: what I think Habermas is after is a theory of how governments can be legitimate in peace. What that requires, in his view, is some form of collective deliberation where actors put aside their differences and agree on some rules: the law.

What about when race and class interests are, as Parikh suggests, “fundamentally antagonistic”, and the unequal ledger of history gives cause for grievances?

Well, all too often, these are the conditions for war.

In the context of this discussion, which started with a concern about the legitimacy of states and especially the United States, it struck me that there’s quite a difference between how states legitimize themselves at peace versus how they legitimize themselves while at war.

War, in essence, allows some actors in the state to ignore the interests of other actors. There’s no need for discursive, democratic, cosmopolitan balancing of interests. What’s required is that an alliance of interests maintain the necessary power over rivals to win the war. War legitimizes autocracy and deals with dissent by getting rid of it rather than absorbing and internalizing it. Almost by definition, wars challenge the boundaries of states and the way underlying populations legitimize them.

So to answer Parikh, the alternative to peaceful rule of law is war. And there certainly have been serious race wars and class wars. As an example, last night I went to an art exhibit at the Brooklyn Museum entitled “The Legacy of Lynching: Confronting Racial Terror in America”. The phrase “racial terror” is notable because of how it positions racist lynching as a form of terrorism, which we have been taught to treat as the activity of rogue, non-state actors threatening national security. This is deliberate, as it frames black citizens as in need of national protection from white terrorists who are in a sense at war with them. Compare and contrast this with right-wing calls for “securing our borders” from allegedly dangerous immigrants, and you can see how both “left” and “right” wing political organizations in the United States today are legitimized in part by the rhetoric of war, as opposed to the rhetoric of peace.

To take a cynical view of the current political situation in the United States, which may be the most realistic view, the problem appears to be that we have a two party system in which the two parties are essentially at war, whether rhetorically or in terms of their actions in Congress. The rhetoric of the current president has made this uncomfortable reality explicit, but it is not a new state of affairs. Rather, one of the main talking points in the previous administration and the last election was the insistence by the Democratic leadership that the United States is a democracy that is at peace with itself, and so cooperation across party lines was a sensible position to take. The efforts by the present administration and Republican leadership to dismantle anything of the prior administration’s legacy make the state of war all too apparent.

I don’t mean “war” in the sense of open violence, of course. I mean it in the sense of defection and disregard for the interests of those outside of ones political alliance. The whole question of whether and how foreign influence in the election should be considered is dependent in part on whether one sees the contest between political parties in the United States as warfare or not. It is natural for different sides in a war to seek foreign allies, even and almost especially if they are engaged in civil war or regime change. The American Revolutionary was backed by the French. The Bulshevik Revolution in Russia was backed by Germany. That’s just how these things go.

As I write this, I become convinced that this is really what it comes in the United States today. There are “two Americas”. To the extent that there is stability, it’s not a state of peace, it’s a state of equilibrium or gridlock.

The meaning of gridlock in governance

I’ve been so intrigued by this article, “Dems Can Abandon the Center — Because the Center Doesn’t Exist”, by Eric Levitz in NY Mag. The gist of the article is that most policies that we think of as “centrist” are actually very unrepresentative of the U.S. population’s median attitude on any particular subject, and are held only by a small minority that Levitz associates with former Mayor Bloomberg of New York City. It’s a great read and cites much more significant research on the subject.

One cool thing the article provides is this nice graphic showing the current political spectrum in the U.S.:

The U.S. political spectrum , from Levitz, 2017.

In comparison to that, this blog post is your usual ramble of no consequence.

Suppose there’s an organization whose governing body doesn’t accomplish anything, despite being controversial, well-publicized, and apparently not performing satisfactorily. What does that mean?

From an outside position (somebody being governed by such a body), what is means is sustained dissatisfaction and the perception that the governing body is dys- or non- functional. This spurs the dissatisfied party to invest resources or take action to change the situation.

However, if the governing body is responsive to the many and conflicting interests of the governed, the stasis of the government could mean one of at least two things.

One thing it could mean is that the mechanism through which the government changes is broken.

Another thing it could mean is that the mechanism through which the government changes is working, and the state of governance reflects the equilibrium of the powers the contest for control of the government.

The latter view is not a politically exciting view and indeed it is politically self-defeating for whoever holds it. If we see government as something responding to the activity of many interests, mediating between them and somehow achieving their collective agenda, then the problem with seeing a government in gridlock as having achieved a “happy” equilibrium, or a “correct” view, is that it discourages partisan or interested engagement. If one side stops participating in the (expensive, exhausting) arm wrestle, then the other side gains ground.

On the other hand, the stasis should not in itself be considered cause for alarm, apart from the dissatisfaction resulting from ones particular perspective on the total system.

Another angle on this is that from every point in the political spectrum, and especially those points at the extremes, the procedural mechanisms of government are going to look broken because they don’t result in satisfying outcomes. (Consider the last election, where both sides argued that the system was rigged when they thought they were losing or had lost.) But, of course, these mechanisms are always already part of the governance system itself and subject to being governed by it, so pragmatically one will approve of them just in so far as it gives ones own position influence over outcomes (here I’m assuming strict proceduralism are somewhere on the multidimensional political spectrum themselves and is motivated by e.g. the appeal of the stability or legitimacy in some sense).